Datasets
The data, and which model learned from which
Every Hebrish model is trained on recordings from one growing dataset. This page lists the datasets, and shows which revision of the data each model was trained on, so you can see which models are behind.
One speaker's voice. Every recording in these datasets is one person: Daniel Rosehill, an English speaker in Jerusalem with an Irish accent. Help add more voices.
Which model was trained on which data
All current models train on Read-Aloud-Voice-Sentences, at the revision recorded in each training run. The dataset keeps growing, so a model trained on an older revision has not heard the newer recordings.
| Model | Trained on | Data as of | Code-switched speech | Status |
|---|---|---|---|---|
| Parakeet v1.0 · Jachnun run r6-en30 | Read-Aloud-Voice-Sentences 550bfcaa | 2026-10-19 | 339.2 min | latest data |
| Nemotron, checkpoint 2 run r6-nemotron-en30 | Read-Aloud-Voice-Sentences 550bfcaa | 2026-10-19 | 339.2 min | latest data |
| Whisper Small ACFT run small-en-en30-acft | Read-Aloud-Voice-Sentences 36845b0d | 2026-10-17 | 152.5 min | behind not retrained since 2026-10-17 |
| Whisper Hebrish v2 (large-v3-turbo) run v2-en30 | Read-Aloud-Voice-Sentences 36845b0d | 2026-10-17 | 152.5 min | behind not retrained since 2026-10-17 |
| Whisper Hebrish v1 (large-v3-turbo) | English-Hebrew-Mixed-Sentences e7dc91ef | 2025-11-17 | 516 clips | superseded by v2 |
Status checked 2026-10-19: the dataset's latest revision was 550bfcaa (2026-10-19 17:13 UTC). Minutes are the code-switched speech in each training run's mix, as recorded in the run. Parakeet and Nemotron also trained on 95.3 min of the speaker's own English and 48.5 min of LibriSpeech; the Whisper v2 runs on 40.5 and 22.0 min.
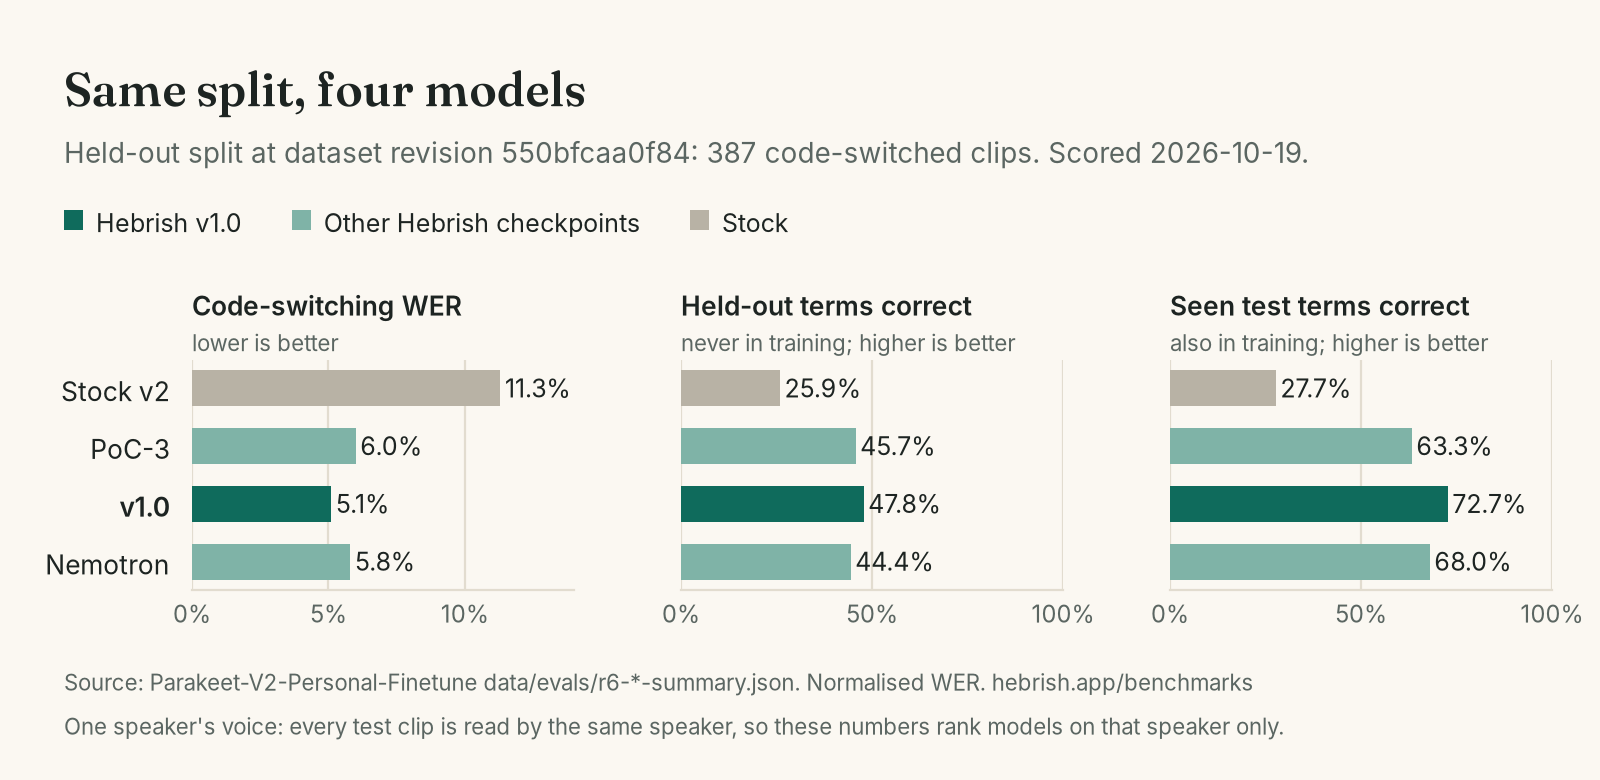
What the latest data bought: the two models trained on revision 550bfcaa, scored on its held-out split. Benchmarks · white paper (PDF).
Recordings
-
Read-Aloud-Voice-Sentences
The parent dataset: every sentence read aloud for the project, on one phone. Code-switched sentences, plain English, tech vocabulary and Yiddish words. The subsets below are copied from it, row for row.
Trains: every current model (table above).
-
English-Hebrew-Codeswitching-Sentences
The code-switched subset: English sentences with Hebrew words in them. A held-out list of Hebrew terms is recorded only in its test split.
Part of: Read-Aloud-Voice-Sentences, so it trains every current model.
-
Yiddish-Sentences
English sentences with Yiddish words in Latin letters (shul, daven, cholent, tachles), the way English speakers in Israel use them.
-
Tech-Sentences
Dictation-style English dense in software, DevOps and AI vocabulary (GitHub, PostgreSQL, kubectl), in the vendors' own casing.
-
English-Hebrew-Mixed-Sentences
Where it started: 516 clips recorded on a desktop on 2025-11-17, three sentences per Hebrew word. 498 of them were later brought into Read-Aloud-Voice-Sentences with their spellings made canonical, so they are part of what every current model trains on.
Trained: Whisper Hebrish v1.
Evaluation
-
English-Hebrew-Codeswitching-ASR-Benchmark
A frozen, versioned test set: 145 clips from the held-out test split. It never changes in place; every result records the commit it was scored against. Never trained on.
Text and outside data
-
hebrew-latin-code-switching
Text only, no audio: English sentences with Hebrew words in Latin letters, with token-level spans marking them. For detecting Hebrew words in English text, not for training speech models.
-
LibriSpeech
Public English audiobook speech, mixed into Parakeet and Nemotron training (with cased, punctuated LibriSpeech-PC transcripts) so the models keep their English. Not made by Hebrish.
The vocabulary these datasets cover is in the lexicon explorer. The models themselves: models and developer notes.