Models · NVIDIA · Parakeet TDT 0.6B v2
 Sabich
Parakeet fine-tune: code-switching plus tech. Trained on everything: the code-switched speech plus tech vocabulary, brand names, numbers and other task recordings.
At a glance
| Base model | nvidia/parakeet-tdt-0.6b-v2 (NVIDIA) |
| Current version | Sabich v1.0, released 2026-10-20 |
| Licence | CC-BY-4.0 · use governed by the terms of use |
| Used by | The Hebrish apps (model picker) |
| DOIs | 10.57967/hf/11101 10.57967/hf/11102 |
Formats and quants
| Repository | Format and files | Version | For | DOI |
|---|---|---|---|---|
Hebrish/Parakeet-TDT-0.6B-v2-English-Hebrew-Codeswitching-All-SubsetsNot publicly visible on Hugging Face (checked 2026-10-20) main | .nemo (NeMo) .nemo, model card and evaluations · access request | v1.0 | NVIDIA NeMo | none yet |
Hebrish/Sabich-sherpa-onnx-int8 | sherpa-onnx int8 encoder, decoder, joiner, about 661 MB · access request | v1.0 | Android, Linux, Windows; what the Hebrish apps run | 10.57967/hf/11101 |
Hebrish/Sabich-GGUF | GGUF Q8_0 730 MB, Q4_K_M 475 MB, F16 1.24 GB · access request | v1.0 | transcribe.cpp (Offline Voice Input, Handy) | 10.57967/hf/11102 |
Hugging Face issues a DOI per repository, so each format can be cited on its own. Repositories, sizes and DOIs checked on the Hub on 2026-10-20.
Versions
| Version | Released | Run | Where | Notes |
|---|---|---|---|---|
| Sabich v1.0 current | 2026-10-20 | r7-all | Sabich-sherpa-onnx-int8 | 560.5 min of the speaker's takes (373.1 min code-switching) plus 62.5 min LibriSpeech replay |
About Sabich
Sabich v1.0 (2026-10-20) is a second Parakeet fine-tune from the same recordings, trained on everything: the code-switched speech Jachnun learns from, plus the tech vocabulary, brand names, acronyms, numbers and currency, Irish-English and other task recordings. It is named after the Israeli pita stuffed with a bit of everything. The Hebrish apps offer it next to Jachnun v1.0 and stock Parakeet: pick it in the model picker if you dictate both English with Hebrew words in it and tech-heavy English. Still one speaker's voice.
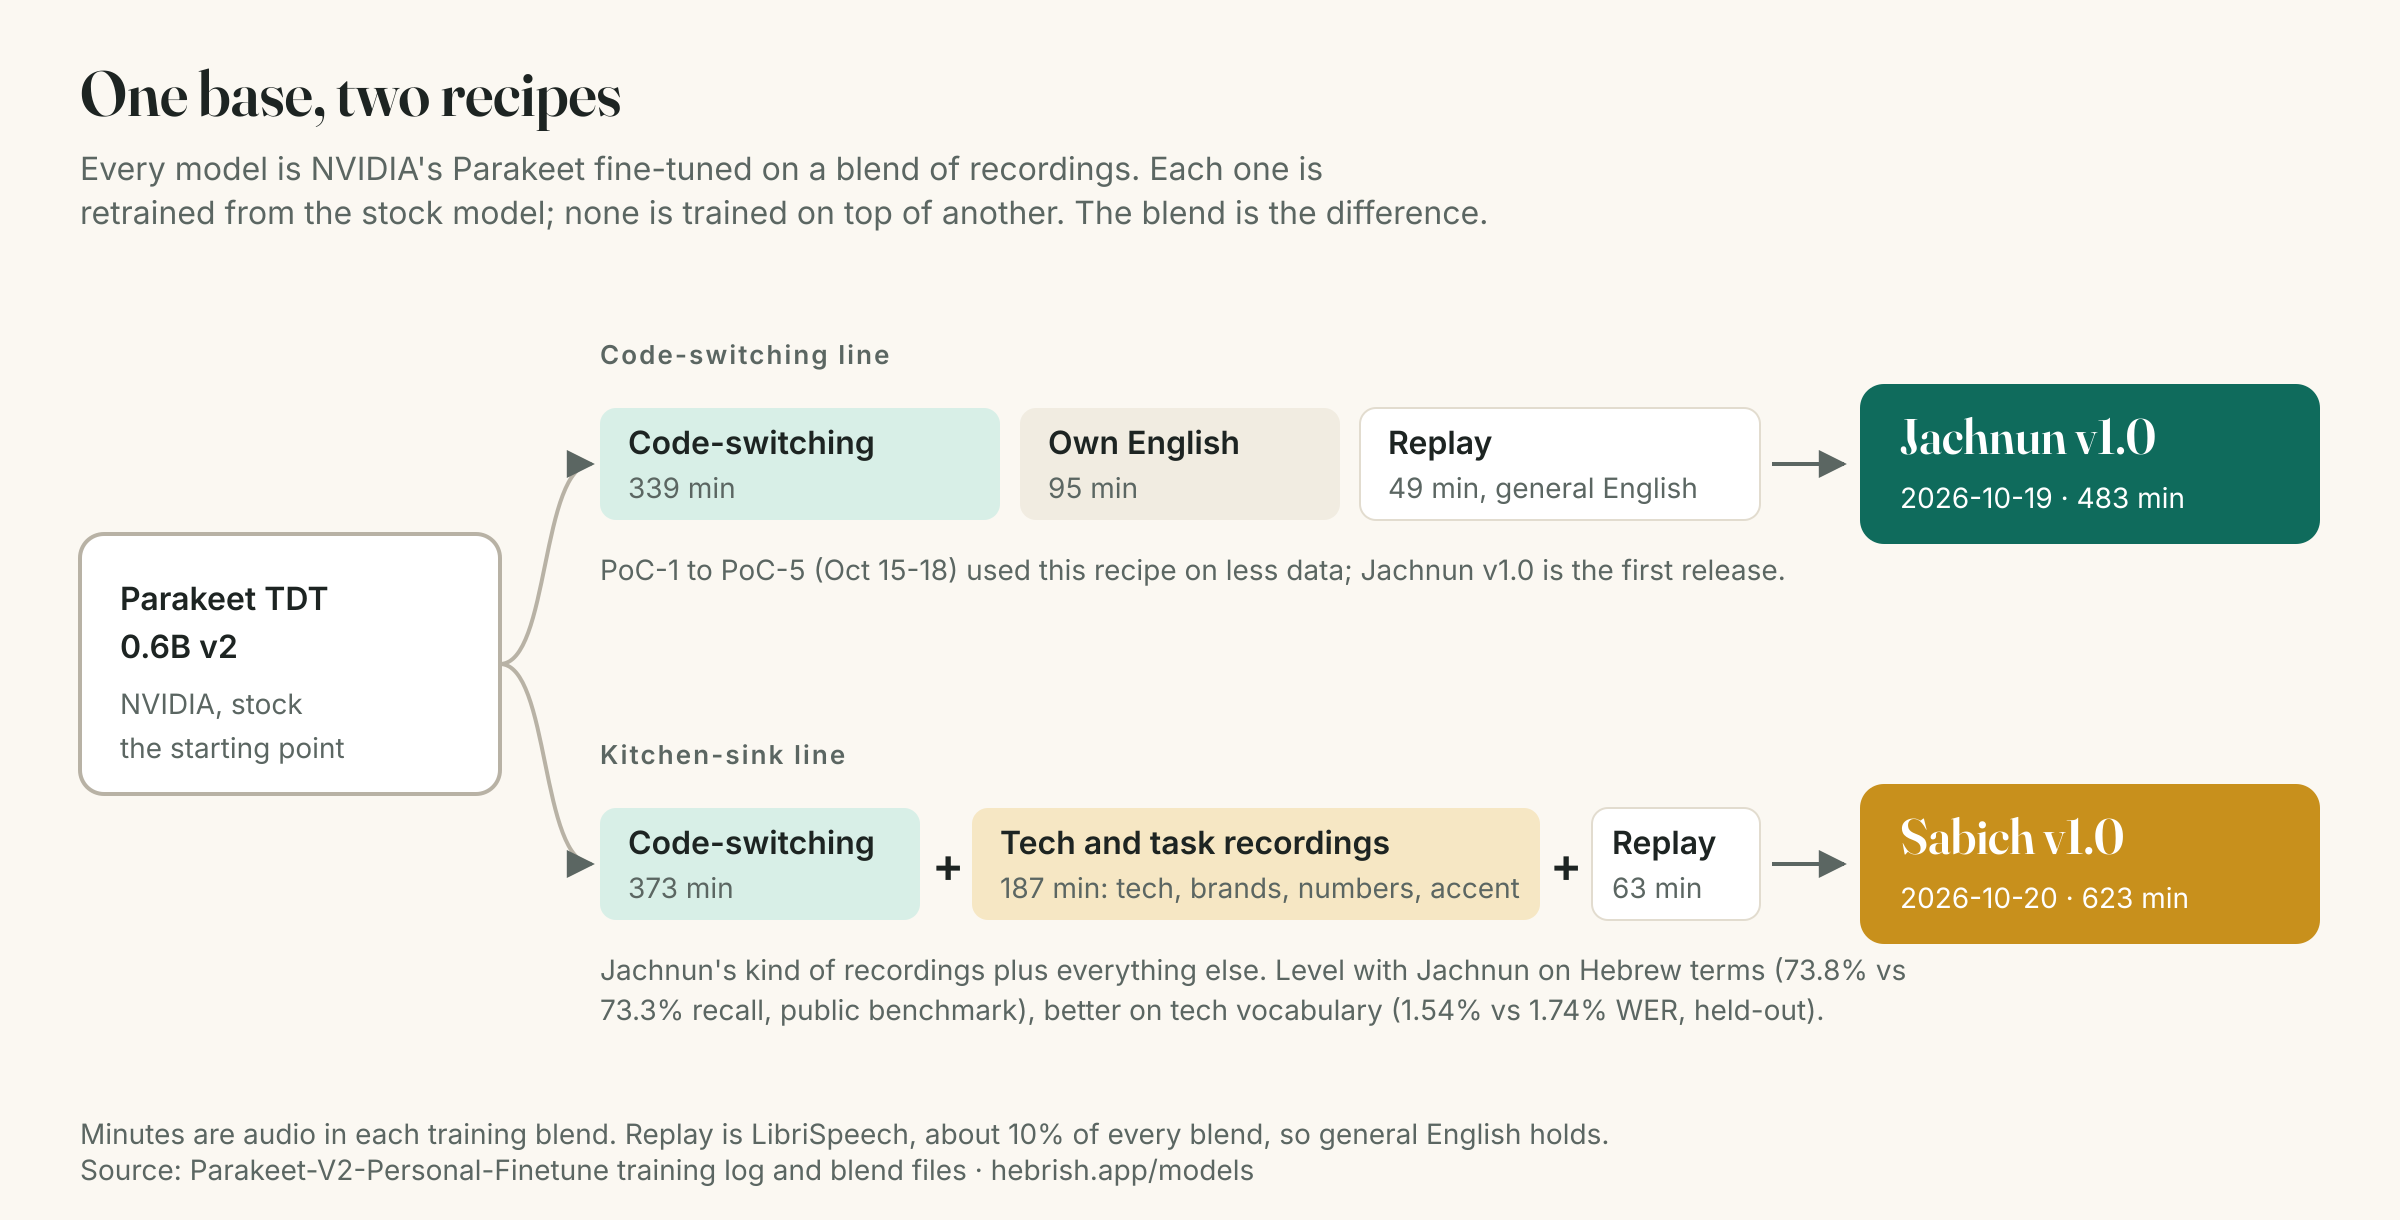
On the public benchmark it is level with Jachnun v1.0: 73.8% term recall (Jachnun 73.3%), 68.4% on unseen terms (70.1%), 3.3% WER (3.3%), 2.0% English control WER (2.2%). The differences are within noise. On the tracker's held-out split at dataset revision f956dbb1 (all three scored on the same clips, normalised WER):
| Model | Code-switching WER (422 clips) | Held-out Hebrew terms correct | Tech WER | Own English WER (84) | LibriSpeech WER (200) |
|---|---|---|---|---|---|
| Stock Parakeet v2 | 11.82% | 23.77% | 2.51% | 2.81% | 1.23% |
| Jachnun v1.0 | 5.42% | 46.91% | 1.74% | 1.56% | 1.20% |
| Sabich v1.0 | 5.30% | 48.15% | 1.54% | 1.62% | 1.30% |
Run r7-all: 560.5 min of the speaker's takes (373.1 min of them code-switching) plus 62.5 min of LibriSpeech replay, 20 epochs on one L40S. LibriSpeech is 0.07 points above stock, about 3 words in 200 clips. Licence CC-BY-4.0, use governed by the terms of use.
Cite
Cite Sabich with its DOI, 10.57967/hf/11101 (Hebrish/Sabich-sherpa-onnx-int8). To cite one format, use that repository's DOI from the table above.
@misc{rosehill_sabich_2026,
  author    = {Daniel Rosehill},
  title     = {Sabich-sherpa-onnx-int8},
  year      = {2026},
  publisher = {Hugging Face},
  url       = {https://huggingface.co/Hebrish/Sabich-sherpa-onnx-int8},
  doi       = {10.57967/hf/11101}
}
Request access
Request access on Hugging Face first. The Sabich repositories are gated: open the repository, sign in, and fill in the short request form there. Requests are reviewed by hand. For non-commercial use, the attestation form covers what we ask. The Hebrish apps download this model from Hebrish's own CDN, cdn.hebrish.app, so using it in the apps needs no access request.
No answer after a few days? Request access here instead, or write to access-requests@hebrish.app. Commercial use, including telephony, needs a commercial licence.